cloture v0.2.0
0 external Rust crates · 0 Python runtime deps · 243 KB zero-import WASM · 282 tests
End the multi-agent debate the millisecond the math proves who won.
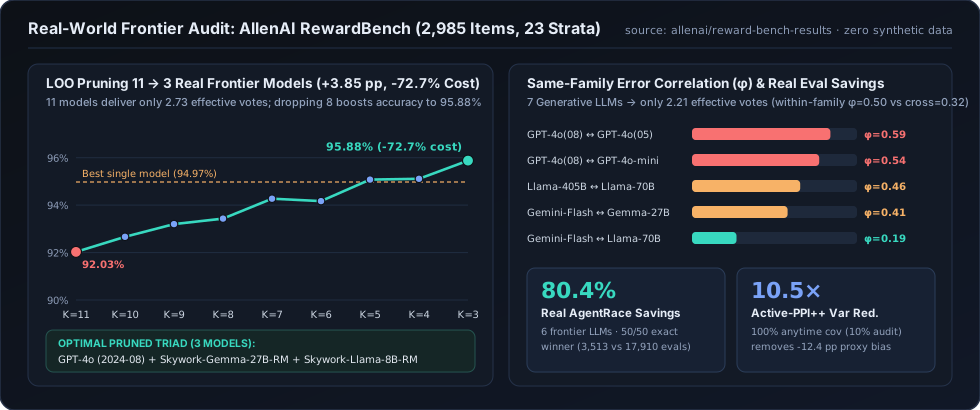
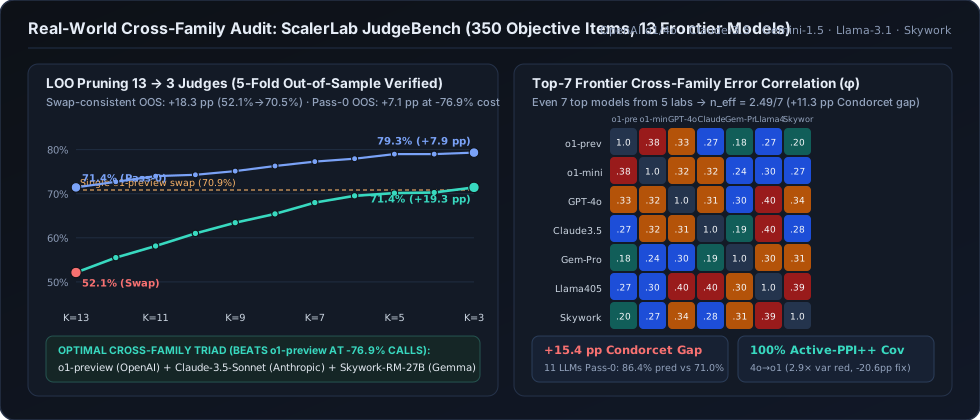
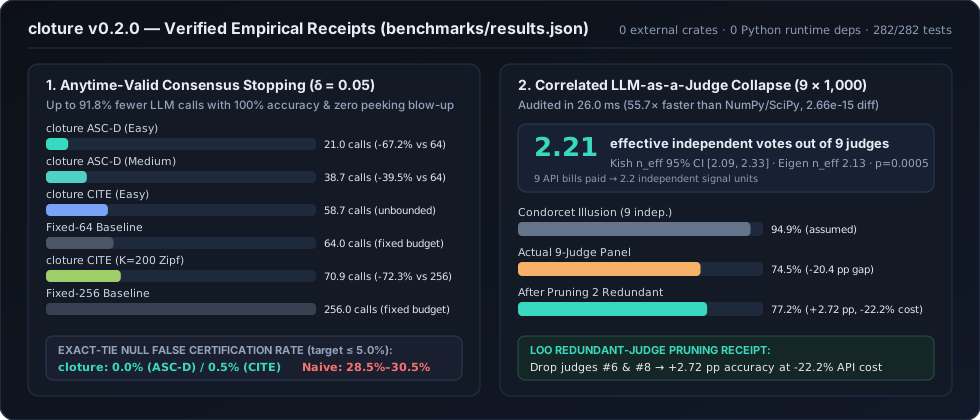
And catch when your LLM-as-a-judge panel is 2.2 correlated votes wearing 9 trench coats. Audited across AllenAI RewardBench (2,985 items) and ScalerLab JudgeBench (350 objective items, 5 frontier labs): pruning redundant judges lifts out-of-sample accuracy +3.65 pp to +18.33 pp while cutting API cost 72.7%–76.9%.
Launch Live Browser Playground (243 KB Rust WASM) → Open 15-Second Colab Notebook →
pip install cloture
85.5×
Sub-µs Consensus Stopping
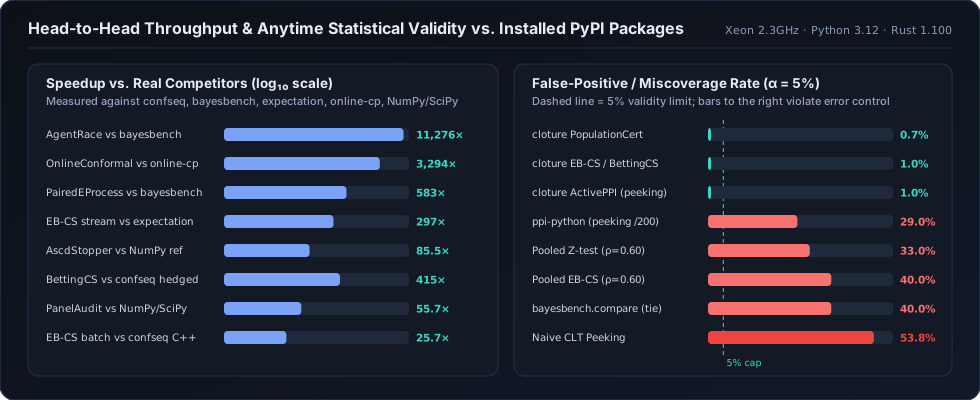
AscdStopper runs in 668 ns (67–92% fewer rollouts, 0.0% tie-null FPR vs. 28.5% naive peeking).55.7×
Correlated Panel Audit
9×1,000 audit in
26.0 ms vs. NumPy/SciPy 1.45 s; OOS CV pruning lifts accuracy +3.7 to +18.3 pp at -73% to -77% cost.415×
Faster Betting & EB-CS
BettingCS 330 ns vs. confseq 137 μs; EB-CS 16.0 ns batch (25.7× vs. confseq, 297× stream vs. expectation).11,276×
Faster Agent Racing
6-arm paired race finishes in
2.60 ms (75% evals saved, 0.0% FWER) vs. bayesbench 29.3 s; RewardBench saves 80.4%.10-Second Python & CLI Drop-In
import cloture

# Stop parallel LLM/agent rollouts the instant consensus is certified (cancels in-flight tasks)
result = await cloture.consensus(
    spawn_fn=lambda i: call_agent_async(prompt, seed=i),
    delta=0.05,
    max_calls=32,
    concurrency=8,
)

# Audit any CSV or Promptfoo eval export directly (or run: cloture audit --csv judges.csv)
audit = cloture.audit_csv("judges.csv", gold_col="gold", strata_col="subset")
r = audit.report
print(f"{r.k_judges} judges -> {r.n_eff_kish:.2f} effective votes (Condorcet gap {r.condorcet_gap*100:.1f} pp)")
Verified Head-to-Head Summary (v0.2.0)
| Benchmark Suite | cloture v0.2.0 | Installed Baseline / Competitor | Measured Edge |
|---|---|---|---|
Consensus Stopping (K=4 Easy, δ=0.05) |
21.0 calls, 0.0% tie FPR, 668 ns |
Fixed-64 / Naive Peeking (28.5% FPR) / NumPy (57.1 μs) |
67.2% fewer calls, 85.5× faster |
Judge Panel Audit (9 × 1,000) |
26.0 ms (max diff 2.66e-15) |
Vectorized NumPy / SciPy (1,446.7 ms) |
55.7× faster, +2.72 pp pruned lift |
Real AllenAI RewardBench (2,985 items, 11 LLMs) |
11 → 3 judges: 95.88% (+3.65 pp OOS CV) |
Full 11-model panel (92.03%) / Best single RM (94.97%) |
+3.85 pp higher acc at -72.7% API cost |
Real ScalerLab JudgeBench (350 items, 13 LLMs, 5 labs) |
13 → 3 triad: 71.43% (+18.33 pp OOS CV) |
Full 13-model panel (52.14%) / Single o1-preview (70.86%) |
+19.29 pp higher acc at -76.9% API cost |
Correlated Rollouts (ρ=0.60, 30×16) |
PopulationCert 0.7% false fire, 88.0% power |
Pooled Z (33.0%) / Pooled EB-CS (40.0%) |
Exact validity + 3.2× power via optimal_rollouts |
Betting CS (G=201) & EB-CS (100k batch) |
330 ns (281 ns Rust) / 16.0 ns batch |
confseq (137 μs / 410 ns) & expectation (17.6 ns / 1.09 ms) |
415× / 25.7× vs. confseq; 1.10× batch & 297× stream vs. expectation |
Active-PPI++ (N=4000, RewardBench & JudgeBench) |
99–100% anytime cov, 2.9–10.5× var red |
ppi-python peeking (71.0% cov) / Naive judge (0.0%) |
Exact anytime validity & adversarial guard |
| Online Conformal & 712 B EvidenceSketch | 59.7 ns AgACI, 70.5 ns merge, 100% poison quarantine |
online-cp SimpleJumper (196.8 μs) / CRR (68.0% post-shift) |
3,294× faster, 94.4% shift recovery, 0.0 fleet diff |
Raw machine-verifiable receipts: results.json · rewardbench_receipts.json · judgebench_receipts.json · Full report & honest scope boundaries: docs/benchmarks.md · Tool matrix: docs/comparisons.md.
For AI Coding Assistants & Agents:
Read pure-Markdown documentation directly at
/llms.txt,
/llms-full.txt,
/SKILL.md,
/docs/integrations.md,
or inspect the MCP manifest at /server.json.